Study Material
Key concepts, anti-patterns and exam traps for each of the five official domains (Exam Guide v1.0, §4).
Domain 1 · 27% of scored content
Agentic Architecture & Orchestration
Design and implement agentic systems using Claude, including orchestration patterns, subagent management, and programmatic enforcement of agent behavior.
Key concepts
- stop_reason
- Tells you why Claude stopped: "end_turn" (finished), "tool_use" (wants you to run a tool), "max_tokens", "stop_sequence". The agentic loop continues while stop_reason is "tool_use" and ends on "end_turn".
- Agentic loop pattern
- Send messages, check stop_reason; on "tool_use" execute the tool(s), append tool_result blocks and call again. Do not parse assistant text or use arbitrary iteration caps as the primary stop signal.
- Task tool & subagent context
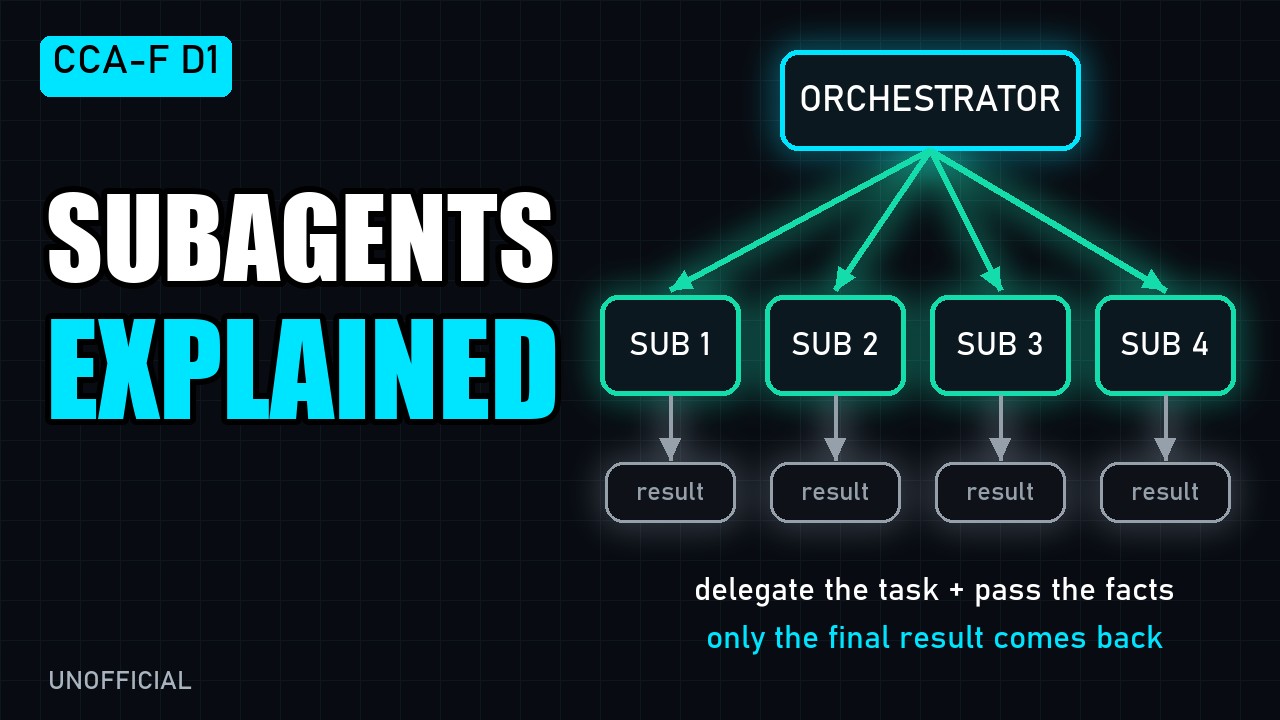
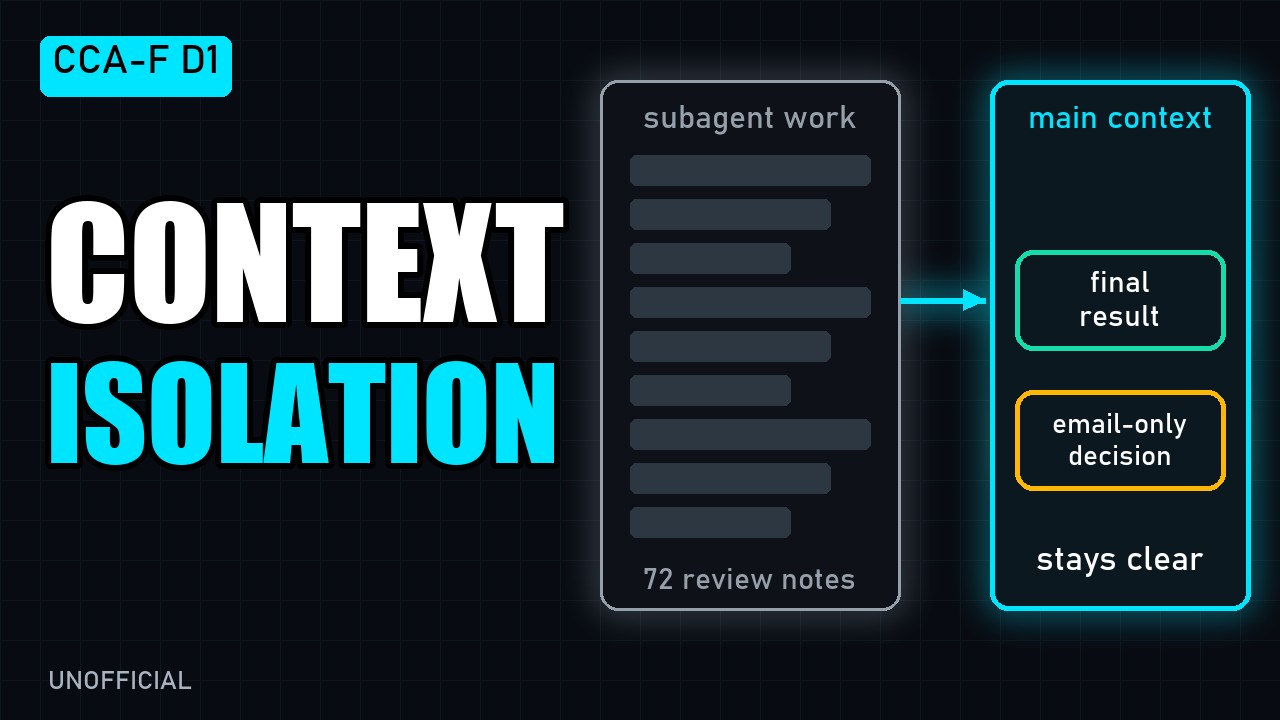
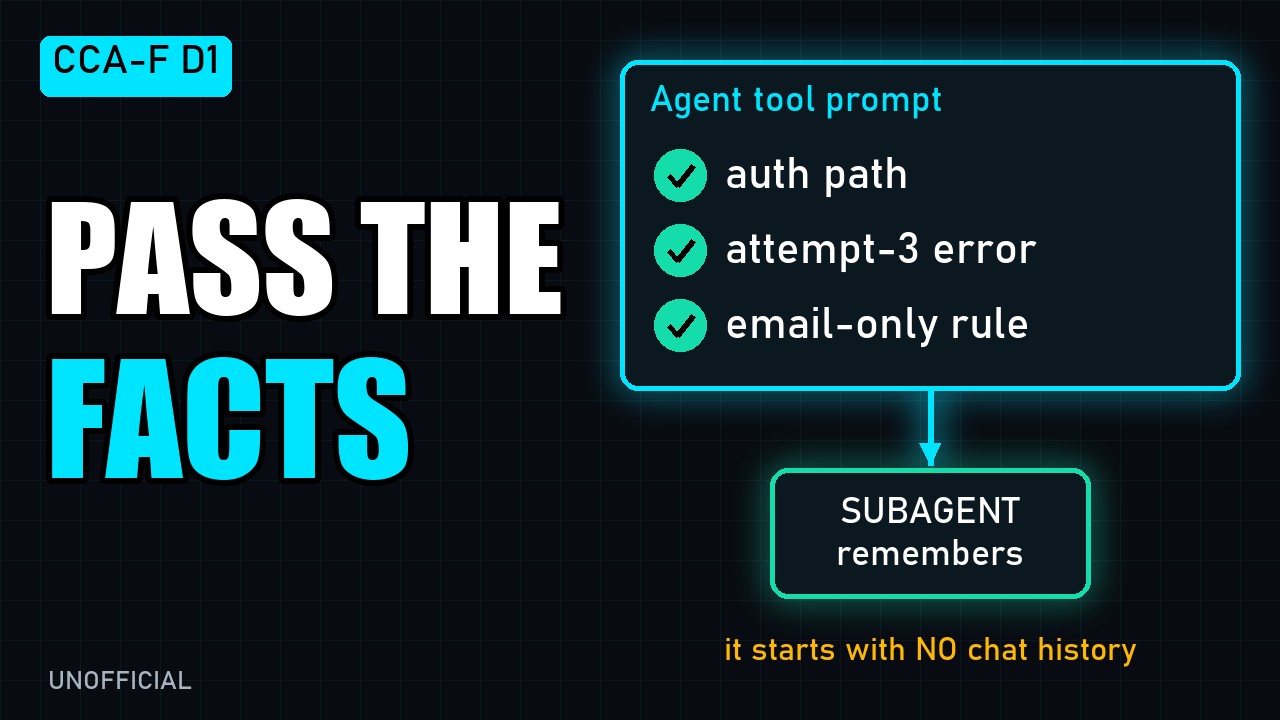
- The Task tool spawns a subagent with its own context window. The coordinator receives only the subagent result. Subagents do NOT inherit the parent conversation — pass findings and context explicitly in the prompt.
- AgentDefinition & allowedTools
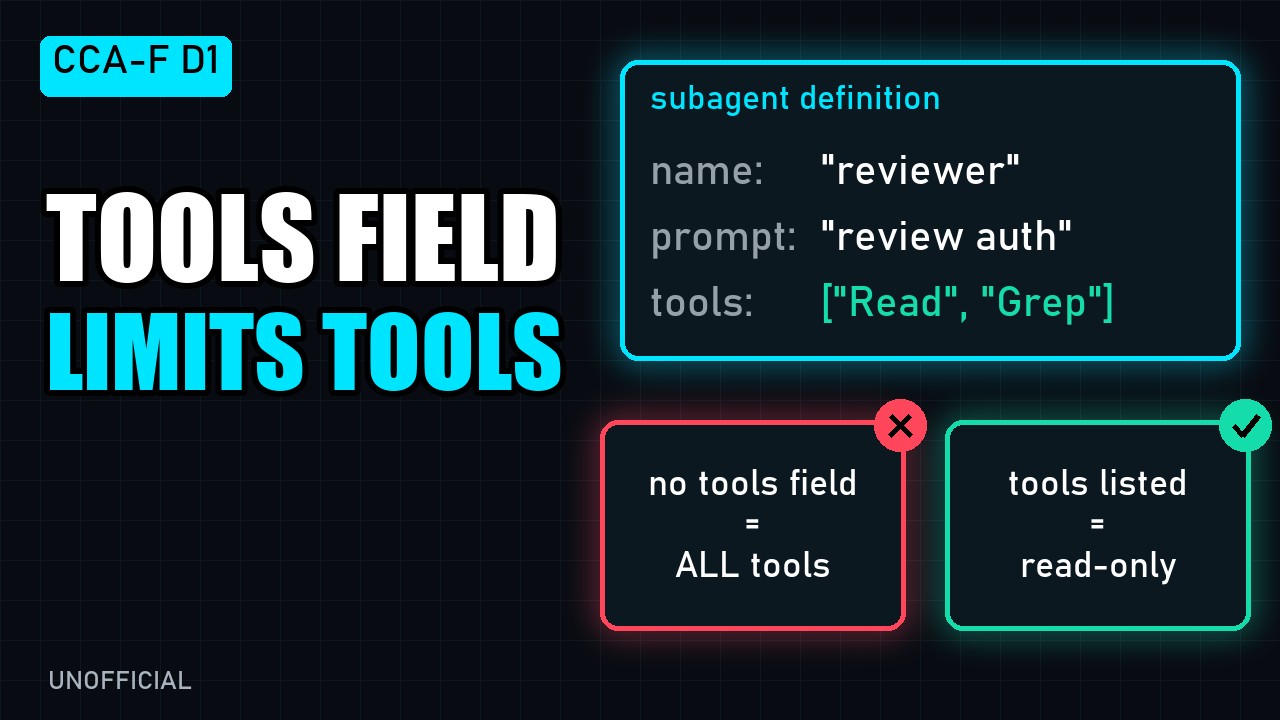
- Subagents are configured with an AgentDefinition (description, system prompt, tool restrictions). A coordinator needs "Task" in allowedTools to spawn subagents.
- Parallel subagents
- Emit multiple Task tool calls in a single response to run independent subagents in parallel; the coordinator synthesizes results.
- Hooks
- Hooks run deterministically outside the model. PreToolUse runs before a tool call and can block it (exit code 2); PostToolUse runs after a call (e.g. to normalize results, lint, log) and cannot prevent it.
- Programmatic enforcement
- When a business rule must hold every time (e.g. verify identity before refunds), enforce it in code or hooks; prompt instructions are probabilistic.
- Sessions: --resume & fork_session
- Resume named sessions with --resume to continue work; fork_session branches from a shared baseline to explore alternatives. Start fresh with a summary when prior tool results are stale.
Anti-patterns
- Relying solely on prompt instructions for rules that must always hold
- Assuming subagents see the coordinator's conversation history
- Ending the loop by parsing natural-language text or a fixed iteration cap
- Over-narrow task decomposition that leaves coverage gaps
- Ignoring tool errors and continuing the loop without handling them
Exam traps
- stop_reason "tool_use" means the model wants YOU to execute the tool — it has not run it
- Subagents do NOT inherit the parent conversation — they start with only what you pass them
- To PREVENT an action use a PreToolUse hook (exit 2); PostToolUse runs after the call
- The loop continues until stop_reason is "end_turn", not "stop_sequence"
Resources
Domain 2 · 18% of scored content
Tool Design & MCP Integration
Design effective tool interfaces, integrate MCP servers, and apply best practices for tool descriptions, structured errors and tool distribution across agents.
Key concepts
- Tool descriptions
- Descriptions are the primary mechanism Claude uses for tool selection. State purpose, inputs, example queries, edge cases and boundaries vs similar tools; rename or split overlapping tools.
- isError & structured errors
- Return isError: true on failed tool results, with metadata such as errorCategory (transient, validation, business, permission), isRetryable and a human-readable description. Distinguish "no results" from "access failed".
- Tool distribution
- Too many tools degrade selection — the guide's example is an agent given 18 tools when it needs 4-5. Scope tools to each agent's role; use subagents for other capabilities.
- tool_choice modes
- "auto" (model decides), "any" (must call some tool), {"type":"tool","name":…} (must call that tool), "none". Forced tool use skips any preamble text.
- .mcp.json & ~/.claude.json
- Project-scoped servers go in .mcp.json (committed, shared); personal/experimental servers in user scope (~/.claude.json). Use ${VAR} environment-variable expansion instead of committing credentials.
- MCP resources
- Resources expose read-only content catalogs (docs, schemas, records) to give the agent context without exploratory tool calls; tools perform actions.
- Built-in tools
- Grep searches file contents; Glob matches file paths; Read/Write/Edit for files (Edit needs a unique anchor — fall back to Read+Write); Bash for commands.
Anti-patterns
- Vague or overlapping tool descriptions
- Returning generic "operation failed" errors with no category or retry hint
- Giving one agent every tool in the system instead of scoping per role
- Using tool_choice "any" when a specific tool is required
- Putting credentials directly in .mcp.json instead of ${VAR} expansion
Exam traps
- isError is a field on the tool RESULT, not on the tool definition
- tool_choice "any" means the model MUST call some tool — it is not "auto"
- MCP resources are read-only context; actions belong in tools
- Tool scoping is per agent role — subagents can each have their own small tool set
Resources
Domain 3 · 20% of scored content
Claude Code Configuration & Workflows
Configure Claude Code with CLAUDE.md, rules, skills, slash commands and hooks; choose plan mode vs direct execution; run it non-interactively in CI.
Key concepts
- CLAUDE.md hierarchy
- User (~/.claude/CLAUDE.md, not shared), project (./CLAUDE.md or .claude/CLAUDE.md, shared via VCS) and subdirectory files. Use @import to pull in other files and /memory to see what is loaded.
- .claude/rules/
- Topic-specific rule files. Path scoping is set with `paths:` YAML frontmatter glob patterns (e.g. paths: ["**/*.test.tsx"]) — not by filename — so rules load only for matching files.
- Slash commands & skills
- Project commands live in .claude/commands/ (shared); personal ones in ~/.claude/commands/. Skills live in .claude/skills/<name>/SKILL.md with frontmatter such as context: fork, allowed-tools and argument-hint.
- context: fork
- A SKILL.md frontmatter option that runs the skill in an isolated sub-agent context, so verbose output does not pollute the main conversation.
- Plan mode vs direct
- Plan mode for large, multi-file or architectural changes with multiple valid approaches; direct execution for simple well-scoped fixes. Toggle with Shift+Tab or start with --permission-mode plan (there is no --plan flag). The Explore subagent isolates verbose discovery.
- -p (print/headless) mode
- -p runs non-interactively for CI. Use --output-format json with --json-schema for machine-parseable, schema-conforming output.
- Hook configuration
- Hooks are configured in settings files under "hooks" with events such as PreToolUse, PostToolUse, Notification and more. Each has a matcher and a command; exit code 2 from PreToolUse blocks the call.
- Long sessions
- Use /compact to reduce context in long sessions; delegate verbose exploration to subagents; keep scratchpad files for findings.
Anti-patterns
- Putting every instruction in one massive CLAUDE.md instead of rules and imports
- Relying on directory-level CLAUDE.md for conventions that span many directories (use paths: rules)
- Hardcoding values in commands instead of using $ARGUMENTS
- Running Claude Code interactively in CI instead of -p
- Skipping plan mode for large refactors
Exam traps
- Rule scoping lives in `paths:` frontmatter, not in the rule filename
- .claude/commands/ is shared with the team; ~/.claude/commands/ is personal
- There is no --plan flag — use Shift+Tab or --permission-mode plan
- -p prints to stdout — use --output-format json (and --json-schema) for parsing
Resources
Domain 4 · 20% of scored content
Prompt Engineering & Structured Output
Write precise prompts with explicit criteria and few-shot examples, enforce structured output with tool_use and JSON schemas, run validation loops and batch processing.
Key concepts
- Explicit criteria
- Define exactly what to report and what to skip ("flag only bugs and security issues"). Vague instructions like "be conservative" do not reduce false positives.
- Few-shot examples
- 2-4 targeted examples showing ambiguous cases and the reasoning for the chosen action are the most effective way to get consistent output and handle edge cases.
- tool_use + JSON schema
- Define an extraction tool with a JSON schema and force it with tool_choice; read the structured arguments. Schemas remove syntax errors but not semantic errors.
- Optional/nullable fields
- Make fields optional or nullable when the source may not contain them so the model does not fabricate values; use enums with "other" + detail fields.
- Validation-retry loops
- On a validation failure, retry with the original document, the failed output and the specific error. Retries do not help when the information is absent from the source.
- Message Batches API
- Up to 100,000 requests or 256 MB per batch, 50% cost, most results within 24 hours (no latency SLA). Use custom_id to correlate results. A batch request cannot do multi-turn tool calling. Good for overnight reports, not blocking pre-merge checks.
- Independent review
- A model reviewing its own output in the same session is biased by its reasoning context. Use an independent review instance and multi-pass review (per-file then cross-file).
Anti-patterns
- Free-text output when downstream systems need structured data
- Making every schema field required, causing fabricated values
- Using the Batch API for blocking, latency-sensitive workflows
- Self-review in the same session instead of an independent instance
- No examples when output format consistency matters
Exam traps
- tool_use for structured output works even if the "tool" never executes — you read the arguments
- Batch API: 50% cheaper but up to 24 h, no SLA, no multi-turn tool calls inside a request
- Strict schemas eliminate syntax errors, not semantic ones (e.g. totals that don't add up)
- Self-review in the same context misses its own mistakes — use an independent instance
Resources
Domain 5 · 15% of scored content
Context Management & Reliability
Preserve critical information across long interactions, design escalation and error propagation, and keep provenance and human review reliable in production.
Key concepts
- Progressive summarization risk
- Summaries condense numbers, dates and customer-stated expectations into vague text. Keep a persistent "case facts" block of transactional facts outside the summarized history.
- Lost in the middle
- Models attend best to the start and end of long inputs. Put key findings summaries at the beginning and use clear section headers.
- Tool result trimming
- Large tool outputs crowd the context. Keep only the fields the task needs (e.g. 5 of 40 order fields) before they accumulate.
- Escalation triggers
- Escalate when the customer explicitly asks for a human, when policy is ambiguous or silent, or when the agent cannot make meaningful progress. Sentiment and self-reported confidence are unreliable proxies.
- Confidence calibration
- Model self-reported confidence is poorly calibrated. Use field-level confidence scores calibrated against labeled validation sets, plus stratified random sampling of high-confidence output.
- Structured error propagation
- Subagents return failure type, attempted query, partial results and alternatives so the coordinator can retry, fall back or annotate gaps — never silently return empty success.
- Scratchpads & provenance
- Persist findings in scratchpad files across context boundaries; keep claim-source mappings (URL, excerpt, date) through synthesis so citations survive.
Anti-patterns
- Unbounded context growth with lossy summaries of key facts
- Critical information buried in the middle of long inputs
- Returning raw, untrimmed tool results
- Escalating on sentiment or self-reported confidence
- Swallowing errors or terminating the whole workflow on one failure
Exam traps
- Progressive summarization is a RISK — preserve facts in a case-facts block
- "Lost in the middle" means put key info at the start (and end), with headers
- Self-reported confidence is not a reliable escalation trigger — calibrate on labeled data
- Aggregate accuracy can hide poor performance on specific document types — stratify